
OrcaSAQ-2 shrinks a 27B coding model to about 12GB. We examine its fidelity results, agent benchmarks, and the practical limits of running it on a 16GB GPU.
OrcaSAQ-2 shrinks a 27B coding model to about 12GB. We examine its fidelity results, agent benchmarks, and the practical limits of running it on a 16GB GPU.
DeepSeek V5 rumors unmasked: V4.1-Flash brings Causal Enc-Dec, 890B/tok KV cache & 8B/16B MoE at $0.15/M on 160K Ascends. Frontier AI at 10X lower cost.
TL;DR The “Ollama Moment” for Decision AI: Just as Ollama unlocked local execution for generative transformers (Llama,…
Apple’s M5 Ultra Mac Studio introduces a quad-die silicon packaging topology delivering 1.2 TB/s of unified memory…
Tsinghua University’s ICLR 2026 Cache-to-Cache (C2C) neural fuser eliminates inter-agent text generation to accelerate multi-LLM inference by…
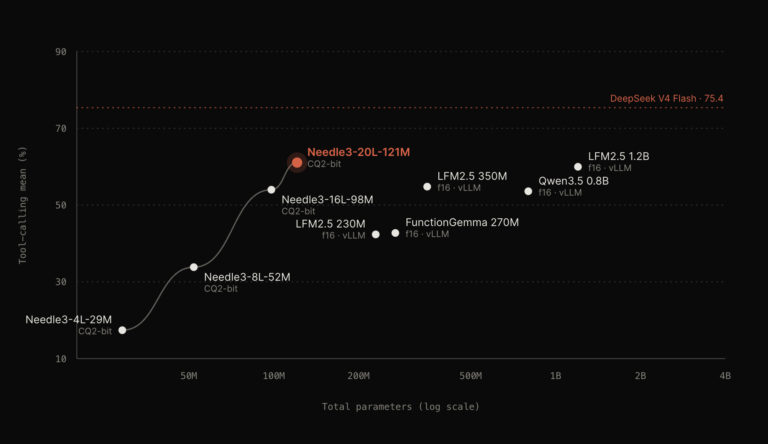
Needle 3 delivers 86% tool accuracy in an 8MB–29MB binary at 4,000 tok/sec. Cactus Compute’s laddered architecture replaces generative chat with edge automation.
ConvAI Innovations’ 0.4B non-autoregressive decision model Laya hit #1 trending on Hugging Face in 48 hours, matching Jev’s sub-35ms speed under Apache 2.0.
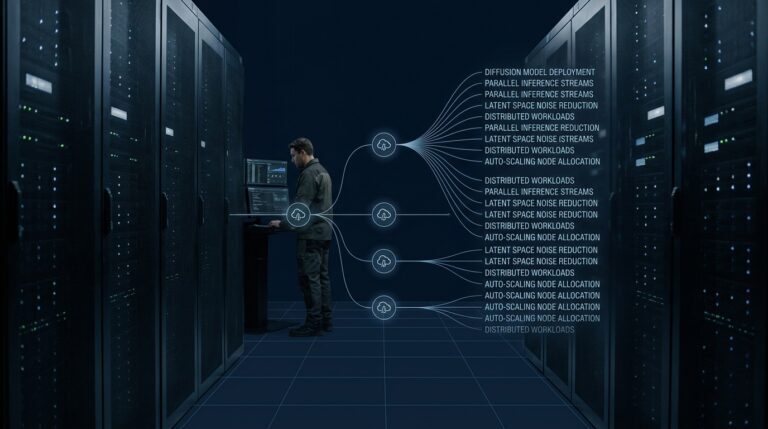
Deploy DiffusionGemma-Jev on Cloud Run with one command. Single-step latency: 35–60ms. Batch@32 throughput: 100–123 req/sec. Costs ~$3/hr active, $0 idle.
Executive Briefing Donald Trump’s warning that “whoever wins AI wins everything” was treated in Washington as an…
DeepSeek is training an 8-trillion-parameter MoE model on 160,000 Huawei Ascend 950DT chips. CEO Liang Wenfeng told investors the domestic chip bet “has to work.”