


Executive Briefing Xiaomi has released MiMo-V2.6, featuring two natively omnimodal sparse Mixture-of-Experts (MoE) models: MiMo-V2.6-Pro (1.02T total…
Executive Briefing Xiaomi has released MiMo-V2.6, featuring two natively omnimodal sparse Mixture-of-Experts (MoE) models: MiMo-V2.6-Pro (1.02T total…
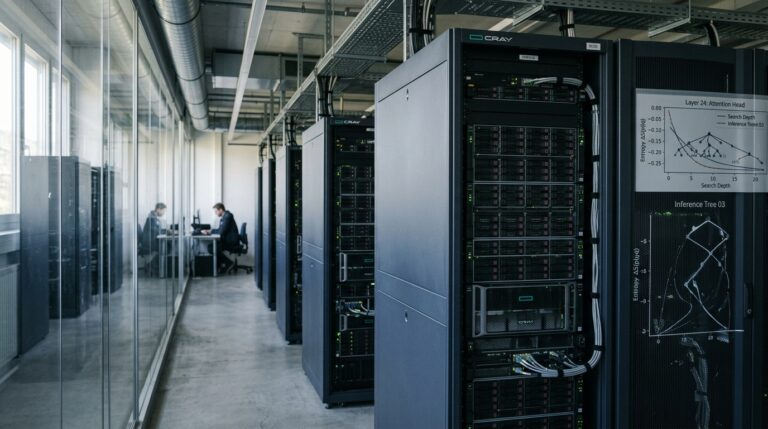
Extending test-time compute can collapse LLM accuracy. Here is the forensic math on Goodhart gaming, attention drift, and why latent recurrent depth wins.
For three years, enterprise engineering forced autoregressive LLMs into programmatic workflows. TypeSafe AI’s Jev proved why we were wrong—and why System 3 is next.
Disclosures broken by developer Lyra confirm Anthropic is closed-beta testing Claude Opus 5.5 (‘claude-wafer-eap’), cutting pricing to $4/$20 per M tokens.
Step 5 Preview redefines the AI Pareto frontier. With a 600B/27B sparse MoE and 1M context, it matches Kimi K3 Max (AA Index 44) at ~$0.71 task cost.
Quick Answer · Featured Snippet Target What is PrismML Ternary Bonsai 2 27B? It is a 1.76-bit…
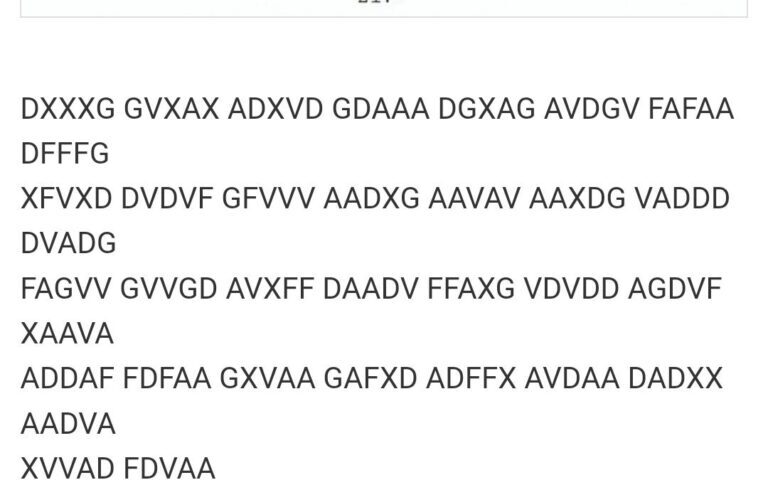
GPT-6 Astra cracked an unsolved 1918 German ADFGVX cipher using historical monograph search and key transposition in 170 chars. Here is the technical audit.
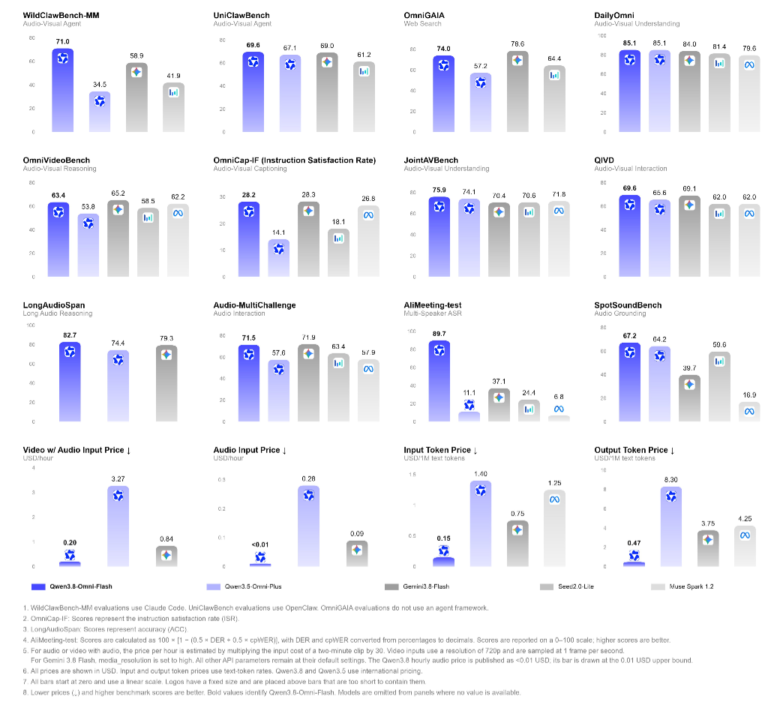
Qwen3.8-Omni-Flash beats Gemini 3.8 Flash on WildClawBench (71.0 vs 58.9) and AliMeeting (89.7 vs 37.1) at 4.2x lower video cost. Read our full teardown.
On September 17, 2026, Z.ai (Zhipu AI) revealed the first empirical, production-grade milestone of Recursive Self-Improvement (RSI):…
Google Dream-RSI cuts code search calls by 161.5× and hits 2,350ms SOTA on Lasso using offline replay simulators—leaving LLM weights 100% frozen.


