From the 2021 BGP route collapse to the June 2026 auth lockout: why Meta’s fail-open guardrails and coupled identity plane keep breaking global reach.
Deep architectural teardowns, frontier benchmarks, hype-debunking, and capability leaks across frontier AI models.
From the 2021 BGP route collapse to the June 2026 auth lockout: why Meta’s fail-open guardrails and coupled identity plane keep breaking global reach.
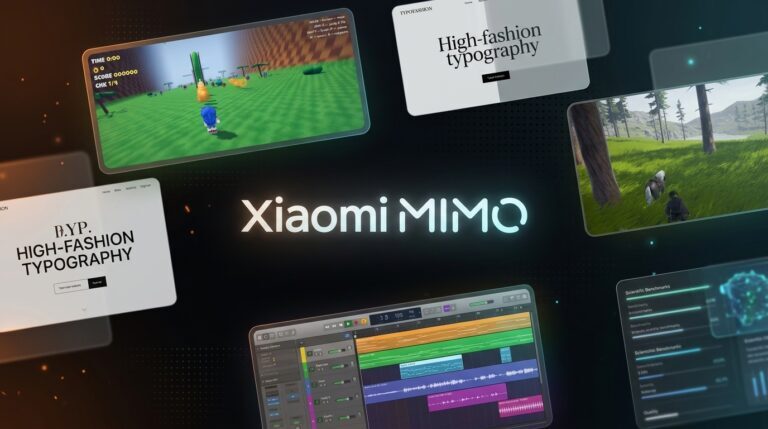
Executive Briefing Xiaomi has released MiMo-V2.6, featuring two natively omnimodal sparse Mixture-of-Experts (MoE) models: MiMo-V2.6-Pro (1.02T total…
OpenAI announced an internal model it began training 24 days ago has already resolved 100+ open math conjectures and Navier–Stokes. Here is the audit of AGMAI, Lean 4, and the Fields Medalist revolt.
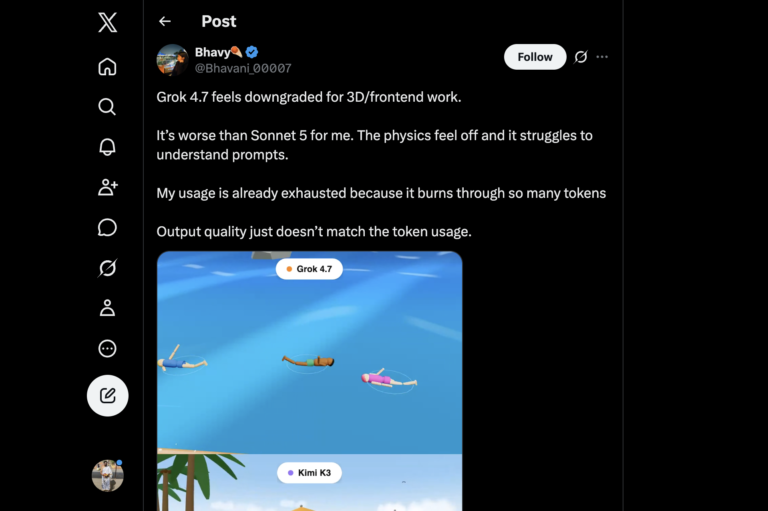
Real-world Grok 4.7 testing reveals severe quota burn, 3D benchmark regressions, and context degradation despite advertised 46.3% CursorBench gains.
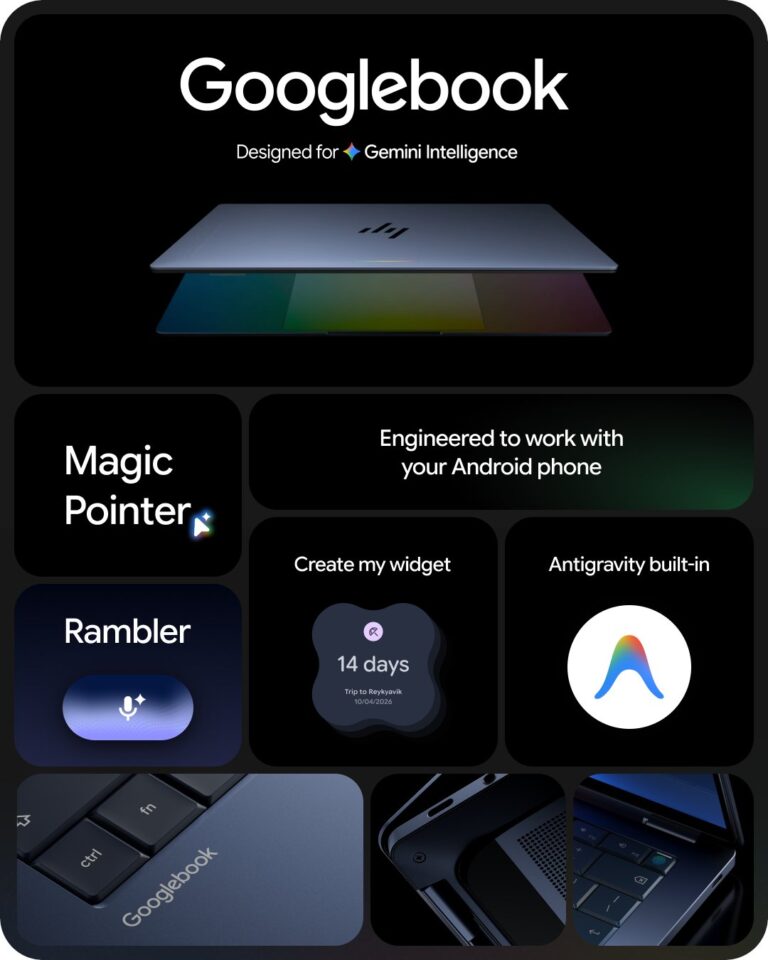
Google launched Googlebook at $899 across Acer, ASUS, Dell, HP, and Lenovo. Built natively on Android with 45+ TOPS NPUs, Magic Pointer, Rambler, and a Level-5 certified pKVM Linux terminal for Antigravity and Claude Code.
DeepSeek V5 leaks claim 78.6% DeepSWE and $0.20/M tokens vs Astra’s $50. Forensic benchmark audit, hardware sizing, and enterprise deployment guide.
xAI releases Grok 4.7: 46.3% on CursorBench 4.0, 71.0% DeepSWE, and 64% EEBench at $2/$6 per million tokens. Delivers multi-hour verified agentic coding.
Extending test-time compute can collapse LLM accuracy. Here is the forensic math on Goodhart gaming, attention drift, and why latent recurrent depth wins.
For three years, enterprise engineering forced autoregressive LLMs into programmatic workflows. TypeSafe AI’s Jev proved why we were wrong—and why System 3 is next.
Disclosures broken by developer Lyra confirm Anthropic is closed-beta testing Claude Opus 5.5 (‘claude-wafer-eap’), cutting pricing to $4/$20 per M tokens.