
Google’s TPU v7 Ironwood scales to 9,216 chips and 1.77 PB of HBM. We examine optical circuit switching, long-context KV cache demands and memory limits.
Deep architectural analysis of frontier AI silicon: Nvidia Blackwell/Rubin, Google TPU, Groq LPUs, and packaging technologies.
Google’s TPU v7 Ironwood scales to 9,216 chips and 1.77 PB of HBM. We examine optical circuit switching, long-context KV cache demands and memory limits.
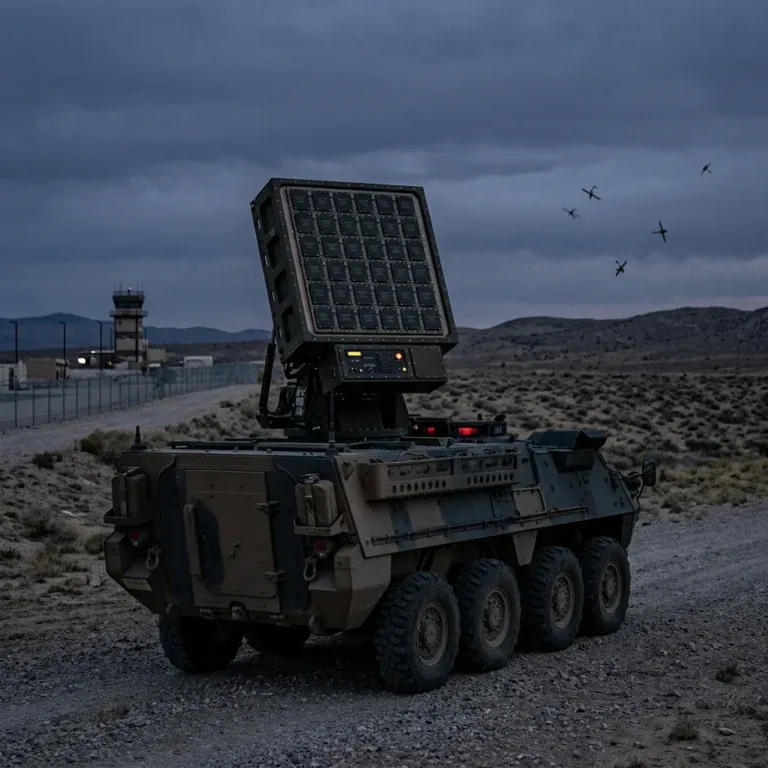
Solid-state GaN HPM arrays disable dozens of drones in microseconds, bypassing 3-5s laser dwell limits and frying unshielded PCB traces at 15-30V surges.
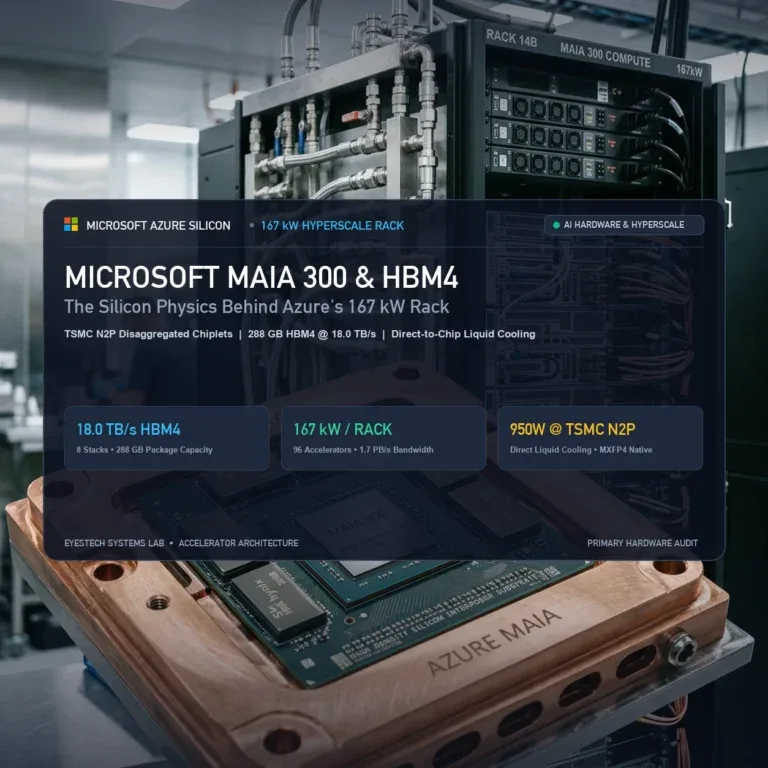
Microsoft Maia 300 pairs 288GB HBM4 at 18 TB/s on TSMC N2P across 96-chip 167 kW racks, bypassing Nvidia memory walls via direct-to-chip liquid cooling.
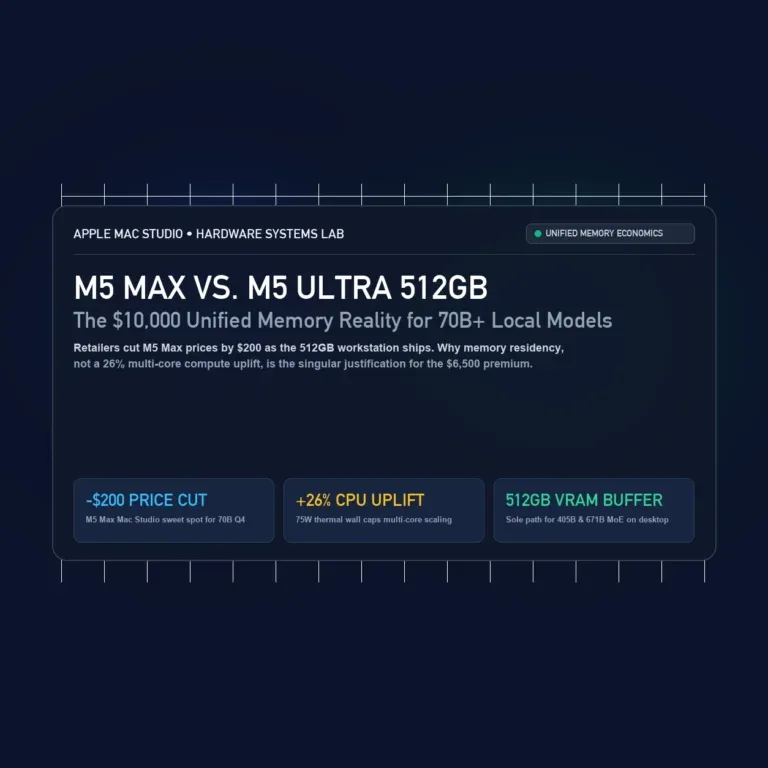
Retailers cut M5 Max Mac Studio prices by $200 as the 512GB M5 Ultra ships at $10,000+. Here is why VRAM residency, not a 26% CPU uplift, dictates the buy.
Drone strikes knocked out two Yandex hyperscale AI data centers and 40% of its fleet. Under Western sanctions, ruined H100 clusters cannot be replaced.
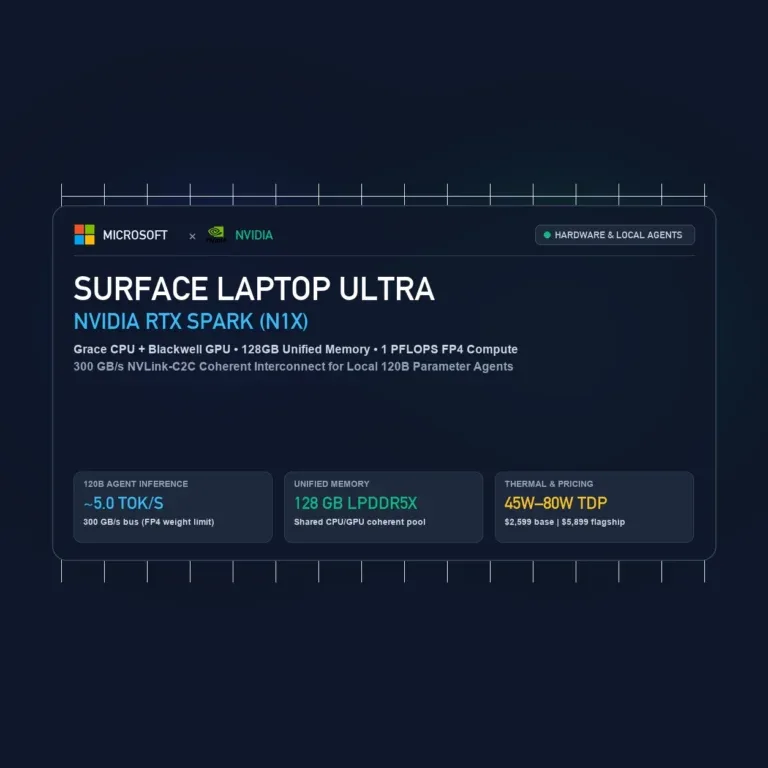
Microsoft and NVIDIA’s Surface Laptop Ultra pairs an Arm Grace CPU and Blackwell GPU via 300 GB/s NVLink-C2C. Here is what 128GB unified memory and 1 PFLOPS FP4 mean for 120B local agents.
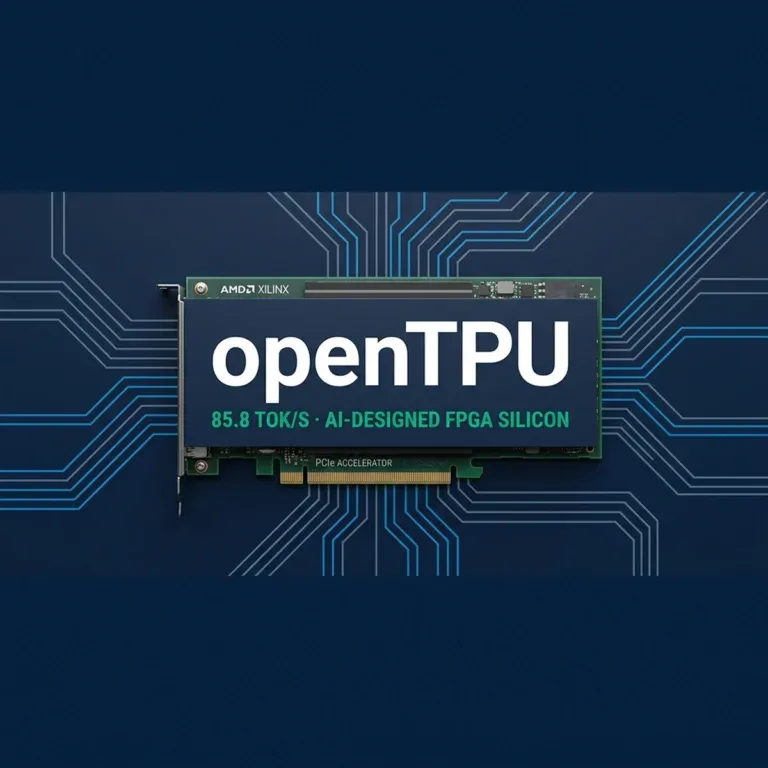
FeSens openTPU runs LFM2.5 at 85.8 tok/s on Kintex-7 FPGA silicon via agent-designed RTL, but off-chip DDR bandwidth caps multi-billion models at 1-4 tok/s.
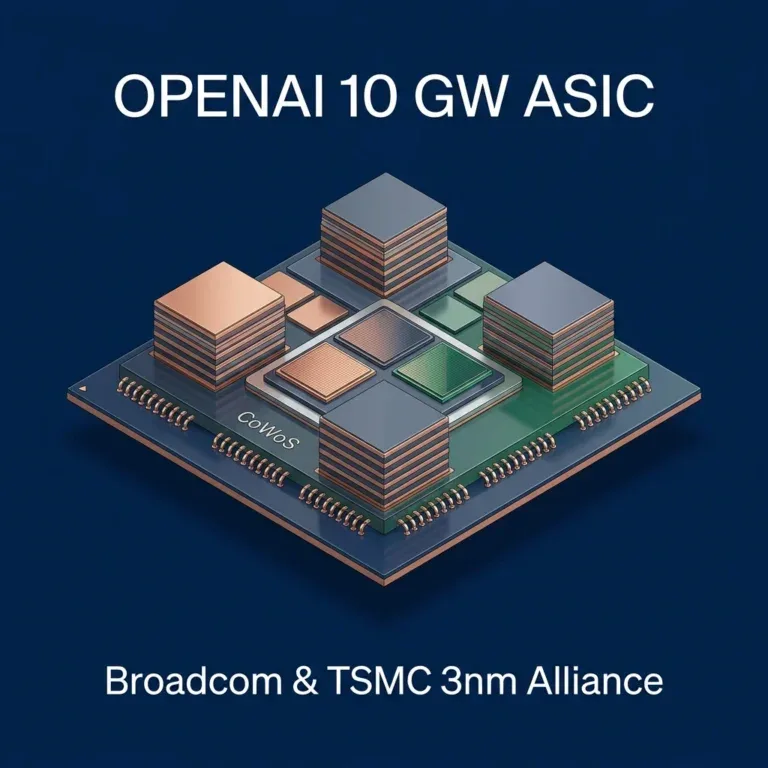
OpenAI and Broadcom booked TSMC 3nm/2nm capacity for a 10 GW inference ASIC deployment by 2029. Here is the CoWoS math, Ethernet fabric, and 60% TCO savings.
DeepGEMM Ascend brings familiar APIs to Huawei Ascend 950. TileLang adds a native backend; 99.8% utilization describes a kernel, not whole-model speed.
DeepSeek has published Ascend 950 versions of two pieces of its model infrastructure: DeepEP-Ascend for moving mixture-of-experts…