
Google DeepMind’s Gemini 4 features a 256k output limit, 2.4-min adaptive reasoning, and TPU 8t Virgo scaling. Full systems audit of the leaked argon checkpoint.
Deep architectural analysis of frontier AI silicon: Nvidia Blackwell/Rubin, Google TPU, Groq LPUs, and packaging technologies.
Google DeepMind’s Gemini 4 features a 256k output limit, 2.4-min adaptive reasoning, and TPU 8t Virgo scaling. Full systems audit of the leaked argon checkpoint.
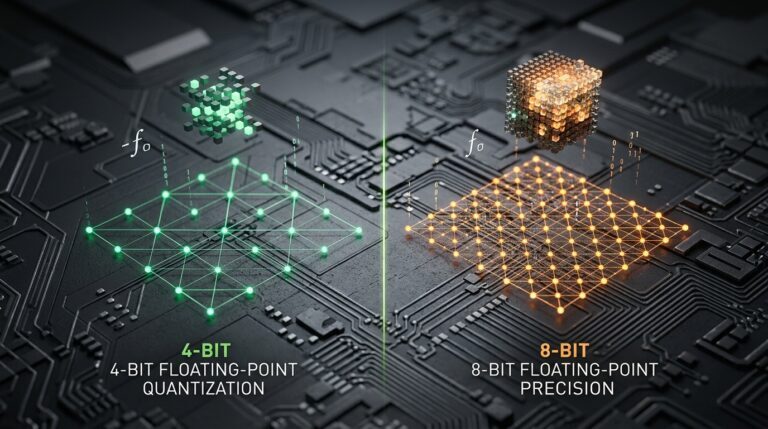
NVFP4 vs FP8 on Blackwell, fact-checked: block-16 scaling, measured speedups, quality limits, mixed-precision recipes and a reproducible acceptance test.
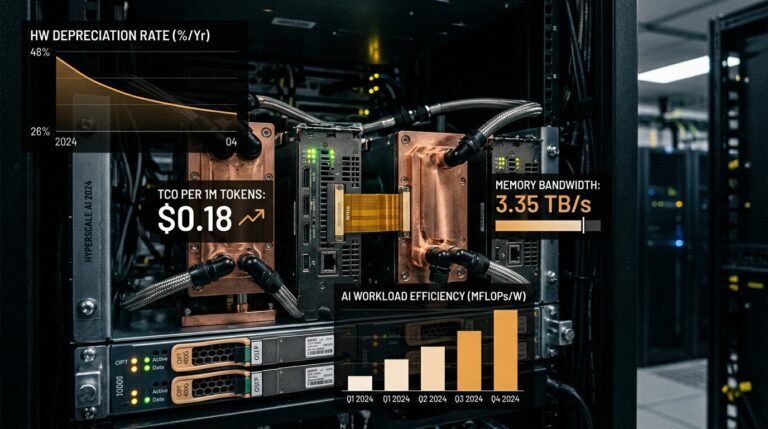
55+ verified benchmarks on AI inference cost, latency, GPU cluster failure rates, and memory bandwidth walls. Download raw 2026 telemetry data.
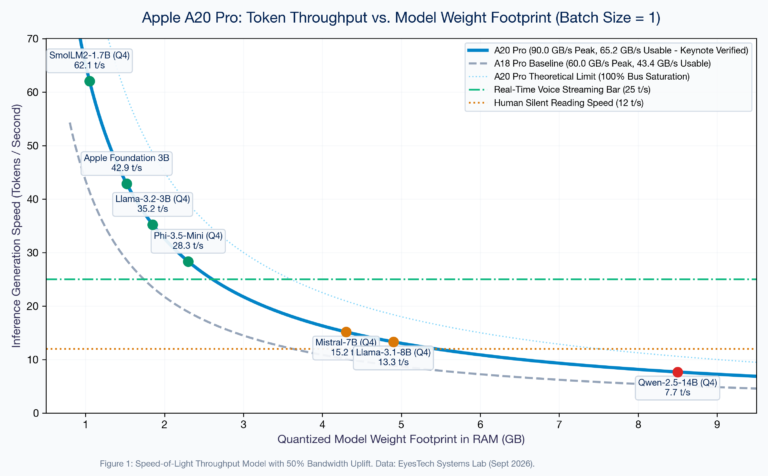
An architectural teardown of Apple’s A20 Pro 2nm GAAFET silicon: testing the 32-core Neural Engine, 65.2 GB/s memory bandwidth wall, copper vapor chamber thermals, and iOS Jetsam limits running 3B to 7B LLMs on-device.
Leaked specifications and canary tests for xAI’s upcoming Grok 4.7 disclose a 2.1T parameter MoE architecture, supplemental pre-training on SpaceX telemetry, Pareto dominance over Claude Fable on CursorBench, and the physical limits of the 200,000-GPU Colossus supercluster.
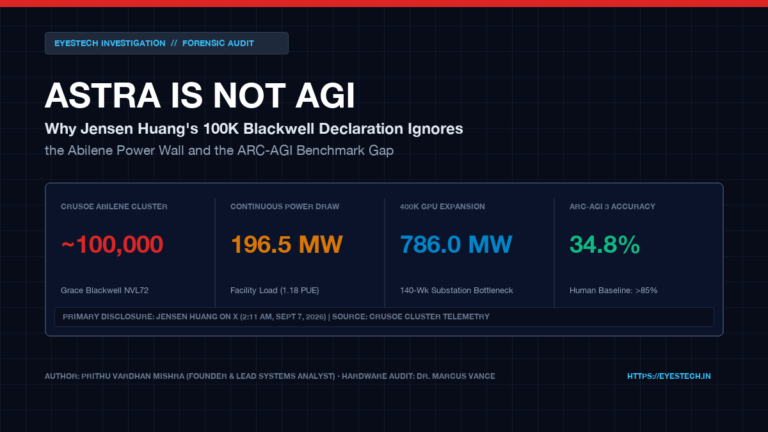
Nvidia CEO Jensen Huang declared that ‘AGI has arrived’ with GPT-6 Astra trained on ~100K+ Grace Blackwell NVL72 in Abilene, Texas. Here is why the claim falls apart under ARC-AGI 3 benchmark audits and the 786 MW substation power wall confronting the 400K GPU expansion.
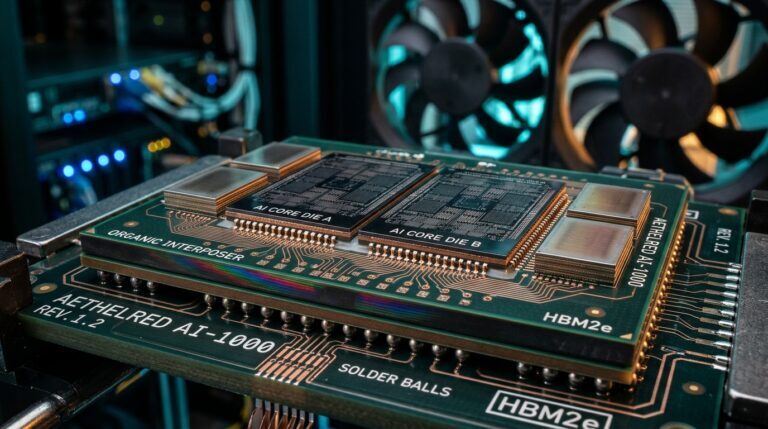
An investigative semiconductor teardown by Dr. Marcus Vance: why package warpage forced Nvidia to cancel the 4-die Rubin Ultra, how screaming chassis fans burn 17% of total rack power in the MGX GB200A air compromise, and the race toward glass core substrates.
The short answer This Pixel 11 Tensor G6 on-device AI review asks a simple question: is Google…

The question keeps returning in geopolitical debates, market briefings, and defense circles: will China invade Taiwan in…